Structured Scorecard for Evaluating UX Writing and Content Design Candidates
A framework for assessing content design candidates beyond polished copy.
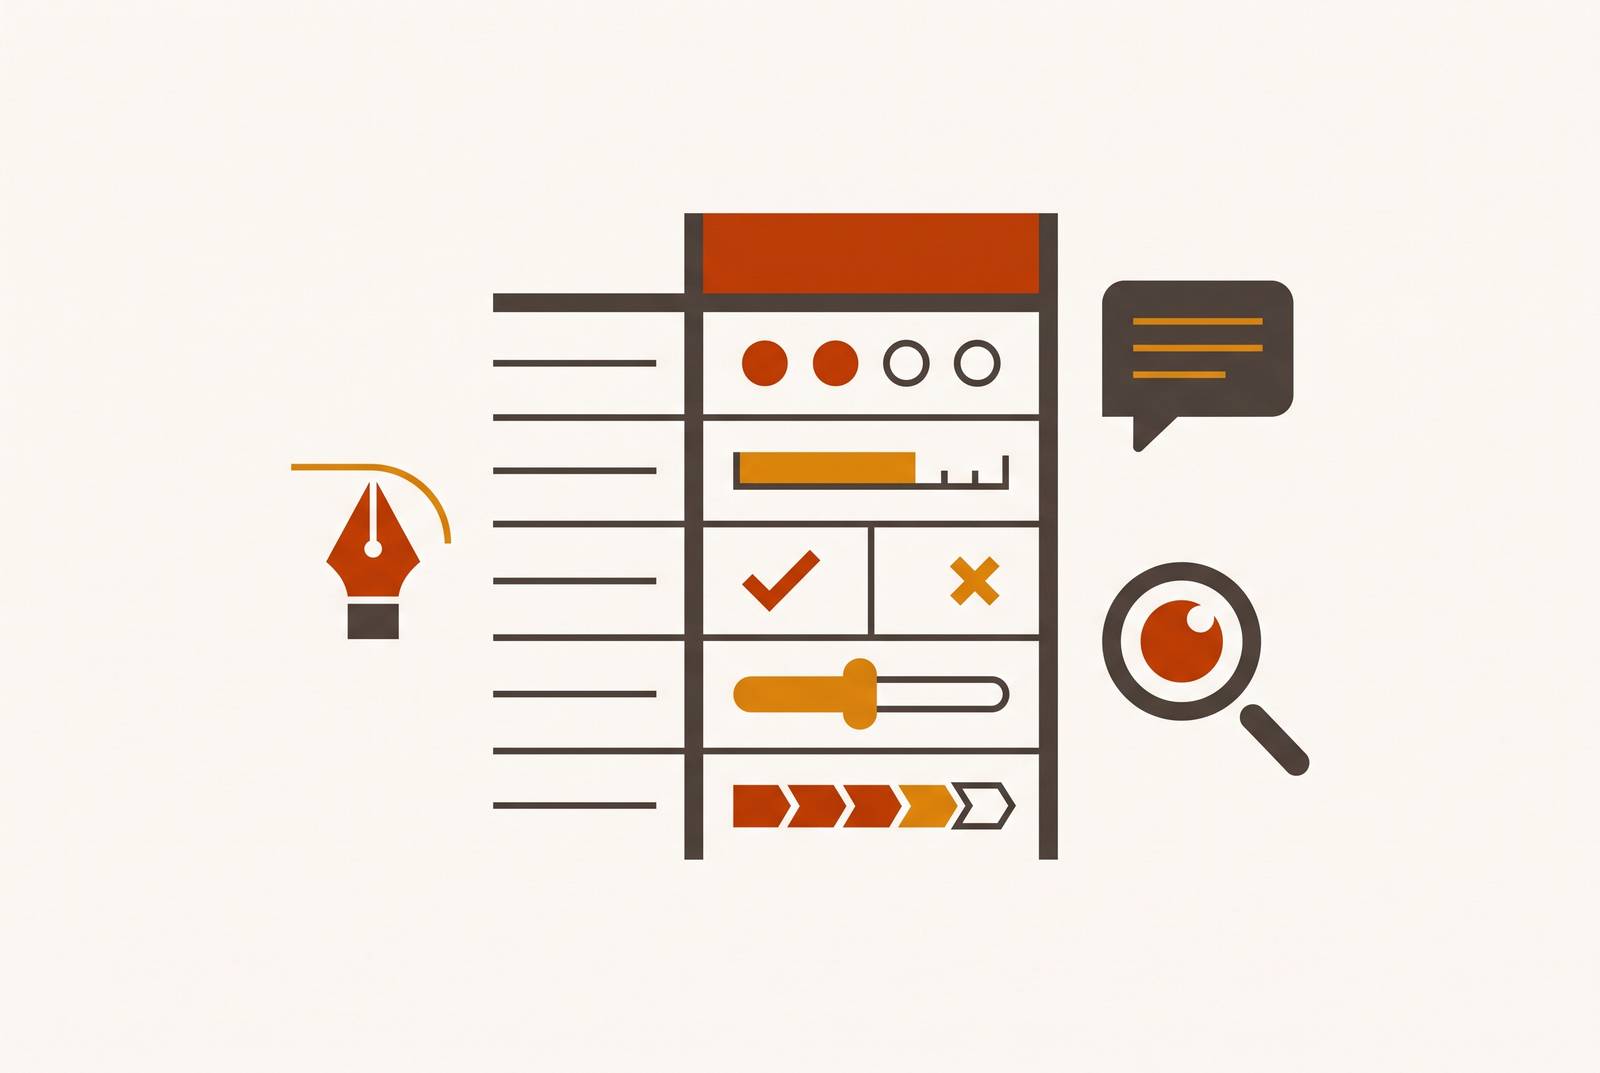
A useful scorecard for UX writing and content design candidates measures more than polished copy. It turns the demands of the job in 2026 into shared criteria, written behavioral anchors, and documented evidence. The goal is a hiring process in which every interviewer assesses the same abilities against the same standard, rather than rewarding whichever strengths happen to match their idea of the role.
Why content design roles are harder to evaluate than they look
An interviewer who still prizes beautiful microcopy may be evaluating a different job from the one they are filling. Content design now includes systems thinking, AI collaboration, structured content, and measurement. Teams also expect influence, prioritization, and cross-functional planning. A candidate can therefore pass an interview focused on copy even if they cannot organize content across a complex product.
The reverse is just as revealing. A strong systems thinker from a non-tech background can fail a process built around polished UI examples, even when their reasoning fits the work. Titles do not resolve this mismatch because “UX writer” and “content designer” sometimes mean the same thing and sometimes describe different scopes. The gap is between what the interview rewards and what the job requires.
What the discipline actually requires now, broken into evaluable dimensions
Four dimensions give the scorecard its foundation. Systems thinking and content architecture are visible in the content types, patterns, naming systems, and rules that keep products consistent as they grow. The evidence can come from work with content models, structured fields, engineering constraints, and design system teams. But work on architecture starts before a model takes shape. A candidate’s explanation should also reveal how they clarified user goals, constraints, and information needs across a journey.
Cross-functional influence and operational maturity show how that work gets done. Did the candidate help shape a product decision, set priorities, or decide how content would be maintained, or did they simply complete the tickets they were assigned? Governance belongs in this assessment because a content system needs decisions about its use. Measurement and evidence of impact form a separate dimension. Here, the evidence is how a candidate defined success, interpreted qualitative and quantitative data, and used the findings to refine flows or patterns.
The fourth dimension is reasoning under ambiguity. It becomes visible when the candidate must decide what to ask, what to assume, and what to leave unresolved. There need not be one correct answer. The useful evidence is how they prioritize and communicate when the information is incomplete, rather than whether they reach the interviewer’s preferred solution.
Why a scorecard without behavioral anchors is just a ranked opinion
Naming those dimensions does not make their interpretation shared. Two interviewers can agree that systems thinking matters but give high scores for very different behavior. One may value a detailed model, while another looks for an explicit tradeoff. Without written anchors, both can give a high score while disagreeing on what it means.
A behavioral anchor makes the standard testable. “Demonstrates excellent systems thinking” offers no observable basis for a rating. “Proposes a content model that surfaces governance logic, maps to engineering constraints, and names one tradeoff they would revisit with more data” does. This consistency is the central advantage of structured interviews over unstructured ones as predictors of job performance. The assessment compares behavior with a written standard.
A complete scorecard needs job-specific competencies, weights, behavioral anchors, evidence notes, and a final hire or no-hire recommendation. A five-point scale is a practical default, provided every level has a written definition. If ratings persistently cluster in the middle, a four-point forced-choice scale can remove the neutral option. Neither scale substitutes for evidence. Notes recording the response behind each rating also make the decision more defensible than a collection of impressions.
The content design scorecard: competencies, weights, and what each score means
For content design, scoring six competencies can turn the four dimensions into criteria for interviews and keep craft and AI proficiency in view. The total should stay within seven to eight competencies, with one or two genuine pass/fail requirements distinguished from the weighted ratings. Weighting changes with the level and scope of the job. There is no useful universal allocation.
Systems thinking and content architecture deserve high weight for senior individual contributors and above. At the top score, the candidate surfaces governance logic, maps constraints, and names tradeoffs unprompted. Cross-functional influence gains weight with seniority too. Its top anchor is a specific example of changing a product decision through content framing.
Measurement and impact evidence earns the top score when the candidate defines a content metric, explains how they would track it, and names a failure signal. Reasoning under ambiguity earns it when the candidate states their assumptions, identifies information that would change their approach, and avoids settling prematurely on a solution. The panel needs to hear how the candidate would recognize that an approach is not working.
Craft and clarity remains a separate competency. Its top anchor is writing that is precise, scannable, and appropriate to context without ornamentation, although its weight should be lower at senior and lead levels than in copy-centered scorecards. AI tool proficiency and collaboration earns the top score through a specific workflow and a clear account of where human judgment is required. Generic familiarity does not meet that anchor. For every competency, the panel must also write the lower rating anchors before use, making explicit which parts of the expected behavior distinguish one score from the next.
A reasonable senior IC pass/fail requirement is evidence of owning an end-to-end content system. Most other criteria should remain weighted so that a single weakness does not automatically eliminate a strong candidate. The panel should score portfolio evidence as part of this process, rather than use polish to screen people out beforehand. What decision did the candidate make, why, and what did they learn? Most roles do not require a specific degree, so the work and the explanation should supply the evidence.
How leveling changes every score on the scorecard
A junior writer working within defined patterns and a senior IC owning an end-to-end flow are not demonstrating the same scope of responsibility. For junior roles, craft and responsiveness to feedback deserve more weight. The evidence may come from work on smaller UI surfaces and from learning to use the product language already in place. That is appropriate to the level being hired. A rubric that expects system ownership would treat a smaller scope of work as a sign of weak ability.
For senior ICs, systems thinking and cross-functional influence move up in weight because the work includes owning flows, running critiques, and partnering with research. Craft becomes table stakes. The scorecard must therefore be versioned by level before the first interview. Adapting it after meeting a candidate makes the standard depend on the person. It can lead to false positives for candidates who meet a lower bar and false negatives for those whose strengths go beyond what the rubric tests.
Calibrating the panel before the first candidate enters the loop
Even a level-specific rubric fails if interviewers have not agreed on how to apply it. The panel should build the scorecard in a shared document before interviews start, rather than work backward to make the criteria fit someone it already likes. Agreement needs to reach the behavioral anchors. For the ambiguous exercise in particular, the panel must decide what “exceptional” looks like before seeing a response.
Independent scorecard submission before the debrief is essential. It limits anchoring around the first strong opinion, halo bias from a standout trait, and later rationalization of an early preference. Strong writing is a risk here because it can raise scores for skills the writing sample never tested. Evidence notes should keep those signals separate. A strong craft rating cannot stand in for proof of systems thinking.
Calibration also needs attention once interviews begin. If one interviewer consistently scores higher or lower than the panel, the panel should revisit the anchors together. Likewise, a panel that cannot reach a clear hire or no-hire decision in most debriefs has reason to question the loop or rubric. Persistent uncertainty can mean the process is not separating the abilities it was meant to assess.
The ambiguous exercise as the scorecard's highest-signal stage
An ambiguous exercise reveals how a candidate works when the brief does not supply every answer. Its uncertainty is deliberate. Designing a multi-step flow, setting out content principles, judging AI output, or explaining how to measure quality can show how a candidate thinks in ways a copy-editing task cannot. The exercise asks the candidate to work through a problem.
The scorecard should record the assumptions and tradeoffs the candidate names, along with what they want to know before they commit. What would change their approach, and why? These are stronger signals for this stage than the aesthetic quality of the output. A quick, elegant solution may still leave the underlying uncertainty unexplored. The panel should use the anchors it agreed on to judge whether the response shows sound reasoning or just sounds confident.
The exercise also serves an authentication purpose. AI-generated writing samples make language quality alone an unreliable basis for attributing skill to the candidate. In-session work or a required follow-up explanation helps the panel assess the reasoning behind the result. Portfolio review follows the same logic by looking for clarity of thinking, self-reflection, and evidence of learning.
Where AI assists and where human judgment is the only viable tool
For a founder or single hiring manager, the useful division of labor is a sequence. AI can help find candidates, parse and rank resumes, draft material, and plan outreach. Portfolio review and ambiguous exercises remain the human-led assessment layer, where interviewers apply the anchors to reasoning and decisions. The distinction is about the kind of judgment required. Processing credentials and titles is not the same task as deciding whether a proposed content model reflects genuine systems thinking.
That boundary also exposes a weakness in automated filtering. Candidates with strong reasoning and non-traditional backgrounds can be missed by tools optimized for familiar credentials. A calibrated human panel using the scorecard provides a correction, rather than merely approving the shortlist’s ordering. Otherwise, the process risks excluding the very systems thinker its copy-focused predecessor would have overlooked.
AI can surface information and recommendations, but the hiring manager remains responsible for questioning those outputs and making the final call. Automation is useful where it reduces volume work without replacing the evaluation the role requires. It cannot supply the shared judgment that calibration and behavioral anchors are designed to establish.
What a realistic candidate pool looks like against this scorecard in 2026
When a senior scorecard asks for systems thinking, AI fluency, cross-functional influence, and the ability to work with measurement, fewer candidates will meet the bar than many hiring plans assume. Technical fluency narrows that pool further. Candidates who can work in repositories, manage AI workflows, and operate directly with engineering teams command a salary premium at every level. A budget for a generalist may therefore fall short for a role that calls for strong technical skills.
Test those expectations before posting. Which criteria are genuine pass/fail requirements, and which are weighted preferences? Treating every competency as mandatory turns the scorecard into a rejection mechanism for candidates who are strong overall but lack one preferred skill. Keeping the distinction explicit makes the standard reflect the work the team actually needs done.
The scorecard also tests whether the role is findable within the proposed budget and timeline. That conversation belongs before the search stalls. When the team agrees on weights, sets anchors for each level, and has evidence for each rating, it can explain why it moves some candidates forward and turns others down. A scorecard built this way makes the search faster because every decision has a documented basis.