Why the Hiring Manager Must Sign the Scoring Logic Before the Algorithm Sees a Single Resume
Explicit hiring criteria signed before screening protects candidates and holds managers accountable.
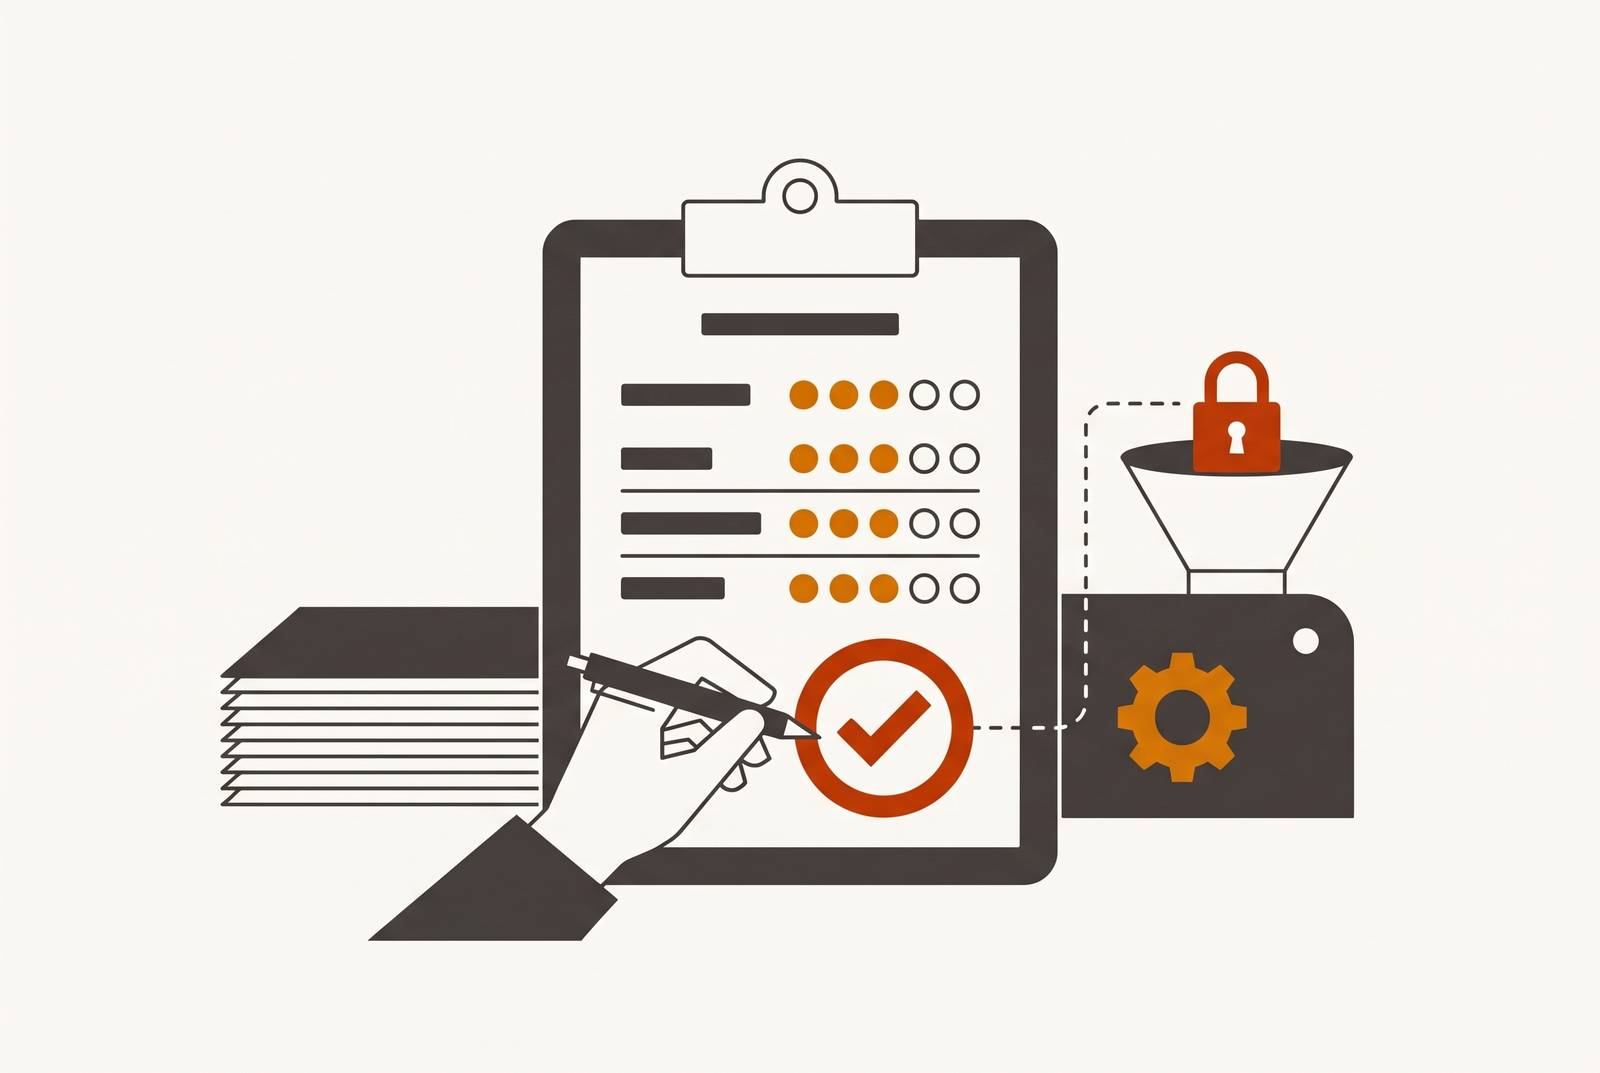
An AI recruiting tool with human-approved hiring standards and an audit trail needs more than a human reviewing its shortlist. The hiring manager must set out, review, and sign the scoring logic before any resume is scored, and a human must approve any later changes. That commitment makes the standard explicit, gives candidate rankings a basis that can be examined, and places responsibility for the hiring criteria with the person who owns the decision.
Why AI screening fails before it starts: the problem of criteria set after the fact
The speed argument for AI screening is seductive because it is real. A tool can produce a shortlist in minutes rather than days, reducing the time spent reading resumes. For hiring managers screening at volume, that is a strong reason to adopt it. But a faster shortlist answers only an operational question. It does not establish that the system selected people for the right reasons.
Things go wrong when the tool starts running before anyone has settled what it should reward. Criteria may come from an old job posting, reflect an unstated preference, or remain vague enough that different reviewers would interpret them differently. The machine still has to evaluate candidates. In effect, the process begins applying a standard before the hiring manager has taken responsibility for choosing it.
That sequence changes what calibration can accomplish. Once candidates have been ranked, a discussion about criteria can become a discussion about whether the shortlist looks right. Familiar backgrounds may make the output seem credible, even when no one can explain why those backgrounds predict success in the role. The results become an anchor for the standard that should have preceded them.
This failure involves both the tool and the people who should decide what it rewards. AI screening is now mainstream rather than experimental, so unresolved judgments can be applied across far more resumes than a human reviewer could read. If the underlying thinking is poor, greater speed makes it harder to contain the consequences.
What AI screening tools actually do when no one has defined what "exceptional" means
Without a clear definition of exceptional performance, screening can fall back on signals that are easy to recognize. Credential proxies, familiar employer names, and keyword density offer patterns to match. A resume can therefore resemble the expected answer without showing that its author has done the work the role requires.
Applicants can also use AI to mirror a job description in their resumes. That makes apparent relevance easier to manufacture, creating false positives when polished wording conceals a mismatch in experience. Meanwhile, filters carried over from past hires can keep other candidates out before scoring begins. The visible shortlist then gives no account of the people the process never allowed through.
Kevin T. Webster’s audit shows why a seemingly fair output is not enough to resolve this problem. Some models that appeared relatively unbiased failed to distinguish relevant from irrelevant candidate experience. The audit calls this the “Illusion of Neutrality”. Near-uniform outputs can satisfy demographic parity because a system makes little meaningful distinction at all.
Xu et al. identify a further distortion in resume screening. LLMs consistently preferred resumes generated by the same model over human-written resumes, introducing a preference unrelated to the candidate’s underlying suitability. Does a high score reflect work that fits the job, a familiar way of presenting it, or the model’s own writing patterns? Without explicit criteria, recycled backgrounds and similar career paths can become the default, narrowing cognitive diversity without anyone deliberately choosing that outcome.
Why the scoring rubric is a bias surface, not just an efficiency input
The scoring rubric connects a definition of good performance to the decisions made about candidates. It is therefore more than an administrative input. What it rewards, ignores, or treats as disqualifying anchors both human and algorithmic evaluation. That makes it a powerful place to prevent bias, but also a place where bias can enter under the appearance of job relevance.
Sapia.ai’s 2026 analysis identifies several points where this happens. Training data can carry past preferences, and the way features are designed can turn inputs into proxies for protected characteristics. Interview data adds another route. Inconsistent scores and unstructured notes can become “ground truth” when fed back into AI models, giving earlier subjective judgments the status of reliable evidence.
Sharma and Molamohammadi show that bias also emerges through interactions between components. A resume parser may function without bias on its own yet contribute to discrimination when combined with particular ranking algorithms and filtering thresholds. Component-level assurances cannot settle the question of integrated outcomes. Their analysis also finds that vendor claims about bias reduction are rarely supported by independent evidence, leaving employers with responsibility for systems they may not be able to inspect fully.
Stanford researchers found in October 2025 that when ChatGPT wrote and rated resumes from the same underlying data, it gave older male candidates higher ratings than female and younger candidates. Such findings make the need for an explicit standard concrete. Without a signed rubric that says what the job requires, there is no benchmark to audit whether differences in treatment are job-related. That absence creates legal exposure, but the prior failure is one of accountability.
How do hiring managers approve scoring criteria before candidates are evaluated?
Approval must be a prerequisite for screening. The hiring manager has to translate implicit preferences into criteria that someone else can inspect and challenge. Signing is the point of commitment. It means accepting responsibility for why each criterion predicts performance in this role, on this team, at this moment.
That work starts by examining the role independently of the previous job description. What must the person be able to do, and what evidence would support that judgment? The rubric needs to distinguish work done, including what a candidate has built, shipped, or changed, from credentials such as employer brand, school name, or title. Those signals are not interchangeable. A familiar credential should not quietly stand in for evidence the manager has never defined.
The same review must take account of the market before sourcing begins. If expectations about compensation, title, or availability conflict with the market, the rubric should expose that conflict before the pipeline is empty. The manager must also agree on what will and will not receive weight, and why. A later change in taste then becomes a visible human override.
Behavioral research described in the brief supports this sequence. Evaluators who had not committed to criteria shifted them to favor the candidate they already preferred, while committing in advance removed the effect. A signed standard creates a record against which later judgments can be compared, so that a change requires an explanation at the time it is made.
The strongest objection: rubrics can launder past bias with greater confidence
A hiring manager can sign the wrong standard. If the rubric derives from the profiles of people previously hired, it may turn past exclusion into future filters with the authority of a documented decision. The objection is serious because consistency can amplify a bad rule. A signature can create false confidence as readily as it can establish responsibility.
Sapia.ai’s account of subjective judgments becoming training inputs explains how a narrow historical definition of success can acquire apparent objectivity. Webster’s audit also shows that context-dependent and intersectional bias can remain even when a system seems neutral. Naming a criterion as job-related does not prove that it is free of proxies for protected characteristics.
Pre-commitment is therefore defensible only if the rubric remains open to examination and revision. An explicit document can be tested against outcomes by demographic group, challenged during regulatory review, and changed when bias is detected. An unwritten preference offers no equally clear object of scrutiny. Results may still show discrimination, but it becomes harder to find the rule that caused it.
The distinction is between fixing a standard in advance and treating it as permanently correct. The first prevents candidate-specific rationalization, while the second can protect a flawed rule from challenge. Whose definition of exceptional does the rubric use? That question has to remain answerable after approval. Building the standard from job requirements rather than past employee profiles gives the commitment a defensible basis, while audit and revision keep documentation from becoming a shield.
The regulatory reality that makes pre-committed, signed criteria a compliance necessity
Employers face legal exposure for AI screening outcomes even when they buy the tool from a vendor. Written, job-related criteria help an employer explain its choices, though a signature alone cannot show that it complies with the law.
Under Title VII, employers are liable for disparate impact caused by AI tools, including tools bought from vendors. That obligation is distinct from EEOC guidance withdrawn in 2025. Webster’s audit and Sanford Heisler Sharp McKnight identify the employer’s exposure under the law. Employers must assess whether the screening process produces unlawful effects even when a vendor describes its product as less biased than human judgment.
The EU AI Act adds rules that take effect in stages. The EU’s executive body says that Article 50 transparency requirements apply from 2 August 2026, while the date for full high-risk compliance for recruitment AI moves to 2 December 2027. The dates address different obligations. They should not be read as a reason to postpone the work of defining and documenting the standards a recruitment system applies.
Sharma and Molamohammadi identify the practical difficulty behind that work. Employers bear legal responsibility without full technical visibility, while vendors control implementations without meaningful disclosure requirements. The employer’s own criteria remain a governance asset it can control directly. Compliance consequently cannot be treated as a project that ends with certification, because bias audits require continuous monitoring as the hiring process operates.
What the human role in AI hiring actually is once scoring logic is locked
Once the standard is approved, the division of labor becomes clearer. AI can screen candidates between the points where people must use their judgment. Humans retain ownership of the definition, any revision, and the final decision. This is not a contest between human and machine intelligence, but a separation between applying a standard and having legitimate authority to choose it.
The hiring manager must first approve the criteria before candidates enter the system. The next is a human review and approval whenever feedback from the hiring loop suggests a change. Locked logic need not mean frozen logic. It means that calibration remains visible and deliberate rather than drifting as reviewers react to the people in front of them.
The final hiring decision also belongs to humans. A resume or structured evaluation alone cannot let AI accurately assess resilience, motivation, communication style, adaptability, or leadership potential. A ranking therefore cannot substitute for the judgment required to make an offer.
Sapia.ai’s framework gives this accountability a practical form through diverse panels, decision logs, and human sign-off on hiring decisions. These are not merely checks performed after an algorithm has done its work. They connect the chosen standard to the people responsible for applying and revising it. For a buyer evaluating an AI recruiter, the decisive governance distinction is therefore not whether a person can view the results, but whether human approval controls the criteria before screening and every deliberate change afterward. The hiring manager’s signature belongs at the start because that is where authority over the standard must be exercised.